

GPU horsepower
for your next drop.
Render. Train. Stream.
Whether you're fine-tuning an image-gen LoRA for a merch capsule, mastering a 12-track EP, batch-rendering 3D product mockups, or hosting a multiplayer demo for your indie game — pick a box, deploy it, and we'll ship root credentials before your espresso cools.
Web Hosting(2)
Small VPS for sites, blogs, and side projects
Portfolio Host — Starter
A right-sized box for the solo creator launching a portfolio, a behance-style gallery, or a one-page shop for prints. Fast NVMe, snapshot rollback, costs less than a coffee subscription.
- 1× IPv4 + IPv6
- Snapshot included
- Root access
Portfolio Host — Plus
Same shape with more RAM headroom for the day a piece goes viral on socials. Built for creators running both a portfolio and a small drop / merch storefront.
- 1× IPv4 + IPv6
- Daily snapshot
- Root access
Production VPS(4)
Real workloads — apps, dashboards, internal tools
Studio Production VPS 24
The everyday server for a working studio — the asset DB, the order pipeline, the API behind the public shop. Postgres + Redis + Node all on one tidy box.
- Dedicated 1 Gbps port
- Auto backups
- DDoS protection
Studio Production VPS 48
For the studio whose tooling outgrew a single VM. Asset search, queue worker, render coordinator, image API — all warm without elbowing each other for RAM.
- Dedicated 1 Gbps
- Auto backups
- Optional managed Postgres
Studio Production VPS 64
Sixteen cores. Sixty-four gigs. The "I never want to think about CPU during a drop" tier for studios shipping merch, prints, or generative campaigns at scale.
- Dedicated 1 Gbps
- Hardware RAID
- IPMI access
Studio Production VPS Max
Top of the shared-compute ladder before bare metal. Built for the studio running a real product alongside its creative work — predictable throughput under campaign load.
- Dedicated 1 Gbps
- Hot snapshots
- Priority support
Storage Servers(5)
Big SSD for backups, archives, media libraries
Project Vault — 300 GB
Cheap, durable bulk SSD for the creator’s raw scans, project archives, and finished-piece backups. Restic-friendly and snapshot-rollback ready when you accidentally delete the wrong folder.
- SFTP / SMB / NFS
- Snapshot rollback
- Auto-expand option
Project Vault — 400 GB
Step up when your raw footage and project files cross 300 GB. Team-wide Nextcloud, photo archives, video raw — all on one snapshotted box.
- SFTP / SMB / NFS
- Snapshot rollback
- Versioned backups
Project Vault — 1 TB
A full terabyte for the studio that keeps every layered PSD, every render frame, every revision. Gigabit uplink for fast restores when a director asks for an old version.
- 1 Gbps port
- NFS / SMB / SFTP
- Restic-friendly
Project Vault — 1.2 TB
Storage plus enough RAM to actually process it. Self-hosted Plex for the studio rec library, NVR for the surveillance feed, or a Lightroom catalog with previews warm.
- 1 Gbps port
- CPU headroom
- Daily snapshots
Project Vault — 1.4 TB Max
The top storage tier with serious compute alongside. For the studio doing photogrammetry, multi-cam ingest, or dedicating one box to its full post-production chain.
- 1 Gbps port
- 50 GB RAM
- Hardware RAID
Dedicated CPU(4)
Whole-box EPYC bare metal for databases + heavy compute
Studio Bare-Metal — Ryzen 12C
Your studio’s own physical machine, nothing shared. Twelve cores at 3.7 GHz hosting a self-managed Postgres, a render coordinator, or a private trading sandbox for your token side-project.
- Bare metal
- IPMI included
- Dual NVMe option
Studio Bare-Metal — EPYC 24C
Server-grade EPYC with ECC RAM and RAID-1 SSD — the grown-up tier for studios with production databases or compliance-bound client work.
- ECC memory
- RAID 1 included
- IPMI / remote console
Studio Bare-Metal — EPYC 32C
Thirty-two cores of 4.2 GHz boost. Build the studio’s tools and serve them from the same box, with NVMe RAID handling render I/O during peak hours.
- NVMe RAID
- 4.2 GHz boost
- Hot-swap drives
Studio Bare-Metal — EPYC 64C
Enterprise bare metal: 64 cores, 192 GB RAM, dual NVMe. For the studio running its own data warehouse, multi-tenant creator SaaS, or heavy nightly ETL across asset libraries.
- Hardware firewall option
- Dedicated 10 Gbps upgrade
- Compliance-ready
GPU Servers(26)
For AI/ML inference, training, render farms
Creator GPU Sandbox — 2 GB
The cheapest GPU-attached box we sell. For the artist learning CUDA, a hardware video encoder for reels, or a headless display server for a remote workstation rig.
- CUDA-capable
- Bare hypervisor allocation
- Snapshot included
Maker GPU Sandbox — 2 GB Pascal
Entry-tier Pascal GPU on dedicated metal. Light CUDA for plugin acceleration, video transcode, low-power lab work for the curious creator.
- Pascal architecture
- Low-power footprint
- Bare-metal dedicated
CAD / Concept GPU — 4 GB
Quadro-class entry GPU for the concept artist running CAD viewports, a light inference loop, or an image preprocessor next to the main creative stack.
- Quadro drivers
- Bare-metal dedicated
- OpenGL + CUDA
Indie Lab Server — 4 GB
Affordable consumer Turing card on dedicated metal. For the maker who wants a real CUDA lab outside the main creative workstation.
- Turing architecture
- CUDA + RTX optional
- Bare-metal dedicated
Creator Render Studio — 8 GB
Entry-class dedicated GPU for your first real generative pipeline. Run an in-studio image generator, batch transcribe voiceovers, or stand up a small detection model for tagging assets.
- CUDA + cuDNN preinstalled
- Docker ready
- Jupyter optional
Bulk Render Server — 24 GB Dual
A pair of older datacenter dies giving the studio 24 GB combined VRAM at a budget price. Great for overnight batch renders, legacy ML pipelines, bulk transcoding.
- Dual K80 dies
- 24 GB combined VRAM
- Bare-metal dedicated
Creator Render Studio — 6 GB Entry
Newest-gen consumer GPU slice for makers experimenting with generative AI on a budget. Entry image generation, small Q4 LLMs, in-house creative chat assistants.
- Blackwell-gen
- GDDR7
- Virtualized GPU slice
Maker Workstation GPU — 4 GB Turing
Turing-gen workstation GPU with a modern driver stack. Low TDP, virtualization-friendly, suited for a creator running a workstation VM or multi-monitor compute.
- Turing architecture
- Low TDP
- Quadro drivers
Visualization Workstation — 16 GB Pro
Modern 16 GB workstation card with ECC VRAM and Quadro-class drivers. Built for the studio running 3D rendering, CAD/CAM, and light inference next to its creative stack.
- ECC VRAM
- Quadro-class drivers
- OpenGL + Vulkan
Creator AI Workstation — 16 GB
16 GB VRAM puts the maker into real ML territory: fine-tune small image-gen models, run 7B LLMs at usable speed, or process video diffusion in batches.
- 16 GB GDDR6
- PyTorch / TF / JAX ready
- NVLink option
Indie Render Lab — 6 GB
Six gigs of GDDR5 paired with a dual-Xeon host — a solid entry-image-gen + 7B Q4 inference rig for the indie creator’s lab.
- 6 GB GDDR5
- Dual-Xeon host
- Bare-metal dedicated
Modern Render Server — 8 GB Ada
Modern Ada architecture with DLSS 3 — a solid all-rounder for the studio running production inference, real-time render, and modern compute on the same box.
- Ada architecture
- DLSS 3
- Bare-metal dedicated
Datacenter Train Server — 32 GB
Datacenter V100 with 32 GB HBM2 and Tensor Cores. Still a workhorse for mid-size studio training and 13B LLM inference at predictable cost.
- 32 GB HBM2
- Tensor Cores Gen1
- NVLink-ready
Creator Render Studio — 8 GB Dedicated
Modern 8 GB GPU on a 24-core host, bare-metal dedicated. For the maker putting a generative feature in front of paying fans where shared slices won’t cut it.
- Blackwell + GDDR7
- 24-core Platinum host
- Bare-metal dedicated
Studio AI Server — 16 GB Pro Dedicated
RTX A4000 on dedicated metal — 16 GB ECC, NVLink, full pro driver stack. The studio’s always-on image-gen or LLM endpoint.
- 16 GB GDDR6 ECC
- NVLink
- Bare-metal dedicated
Creator Workstation GPU — 6 GB Pro
RTX-class GPU on a 128 GB host. RT + Tensor cores give the studio a real entry-level production card for refiner pipelines and small LLM serving alongside creative work.
- RT + Tensor cores
- 128 GB host RAM
- Bare-metal dedicated
Scientific Render Server — 16 GB HBM2
Datacenter Pascal P100 with 16 GB HBM2 and serious FP64 throughput. For studios doing scientific viz, fluid sims, or reference training runs.
- HBM2 memory
- FP64 strong
- Datacenter pedigree
Production Creator GPU — 24 GB Pro
Twenty-four gigs of pro-grade VRAM and 56 GB system RAM — the sweet spot for studios running a production inference endpoint with predictable performance.
- Quadro-class driver
- 24/7 SLA option
- Tier-1 datacenter
Hybrid Creator GPU — 6 GB
RTX 2060 paired with a 40-core host. For the studio running hybrid CPU + GPU pipelines — batch preprocessing into accelerated inference on one machine.
- 40-core host
- RT + Tensor cores
- Bare-metal dedicated
Render Farm Node — 8 GB Ampere
Ampere RTX 3060 Ti with strong tensor throughput per dollar. Solid for an in-studio image generator, a 7B-class LLM endpoint, or one node in a render farm.
- Ampere architecture
- Tensor Cores Gen3
- 2 TB storage
Pro Workstation GPU — 24 GB
Ampere RTX A5000 pro card with 24 GB ECC and workstation-class drivers. For the studio running production inference workloads that have to behave under deadline.
- 24 GB GDDR6 ECC
- NVLink
- Quadro-class drivers
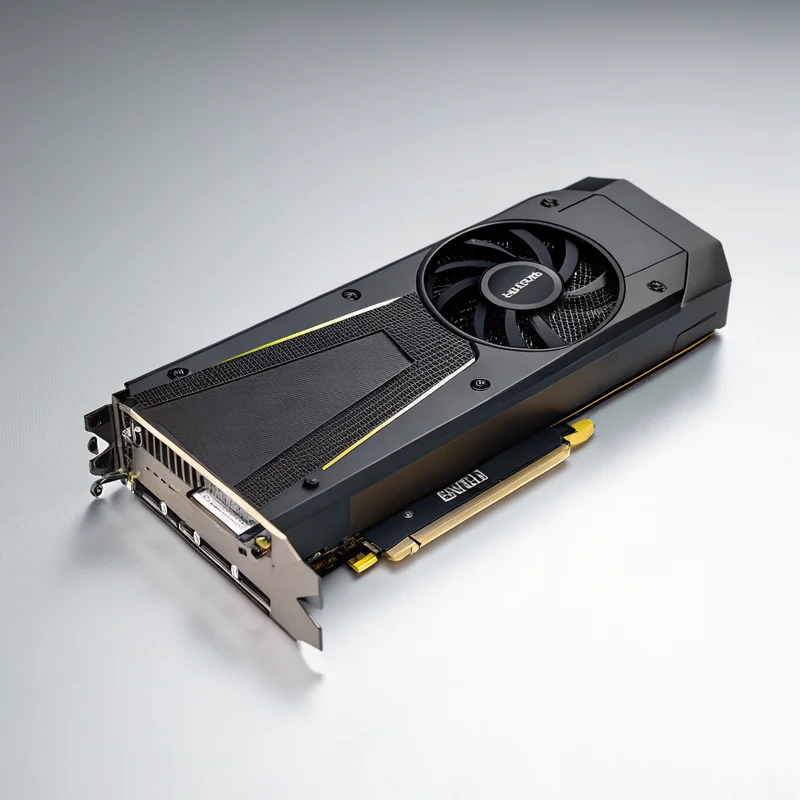
Creator Render Studio — 48 GB
Forty-eight gigs of modern workstation VRAM. Built for 3D artists, video editors, and AI artists rendering portfolio work — chat + image + short-form video can stay warm together.
- 24 GB GDDR6
- NVLink-ready
- Multi-instance GPU
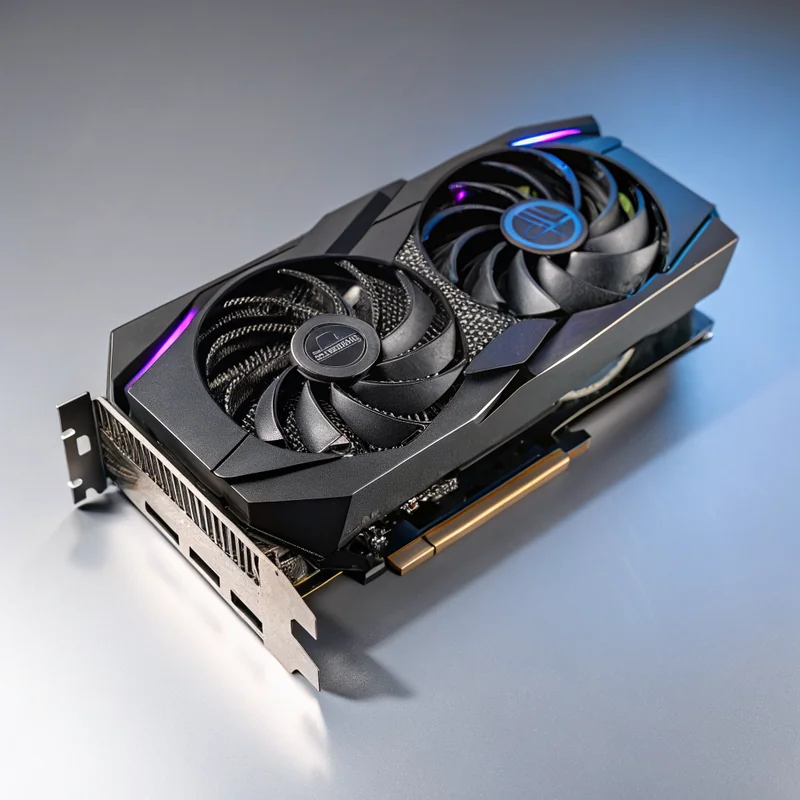
Dedicated Render Server — 24 GB
Dedicated bare-metal 24 GB GPU with 256 GB system RAM and triple-tier storage. For the studio running a private LLM endpoint or a long-running training pass on its own data.
- Dedicated GPU
- 256 GB system RAM
- Triple-tier storage
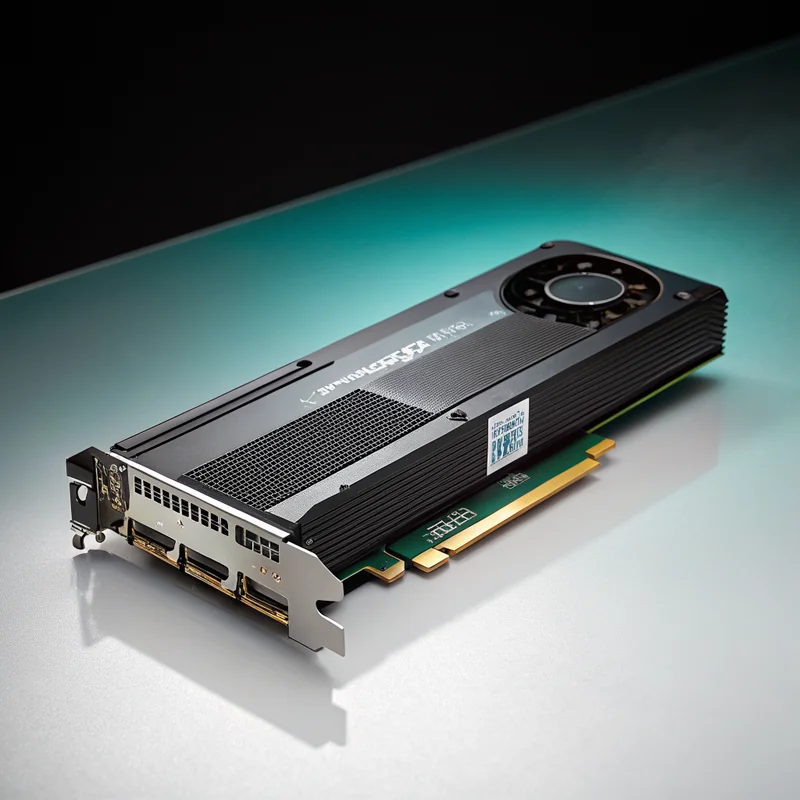
Multi-Modal Studio Server — 48 GB Pro
Forty-eight gigs of ECC VRAM on a dedicated chassis. The studio’s honest tier for "chat + image both warm" — multi-modal inference without resource contention.
- 48 GB GDDR6 ECC
- NVLink
- 24/7 dedicated
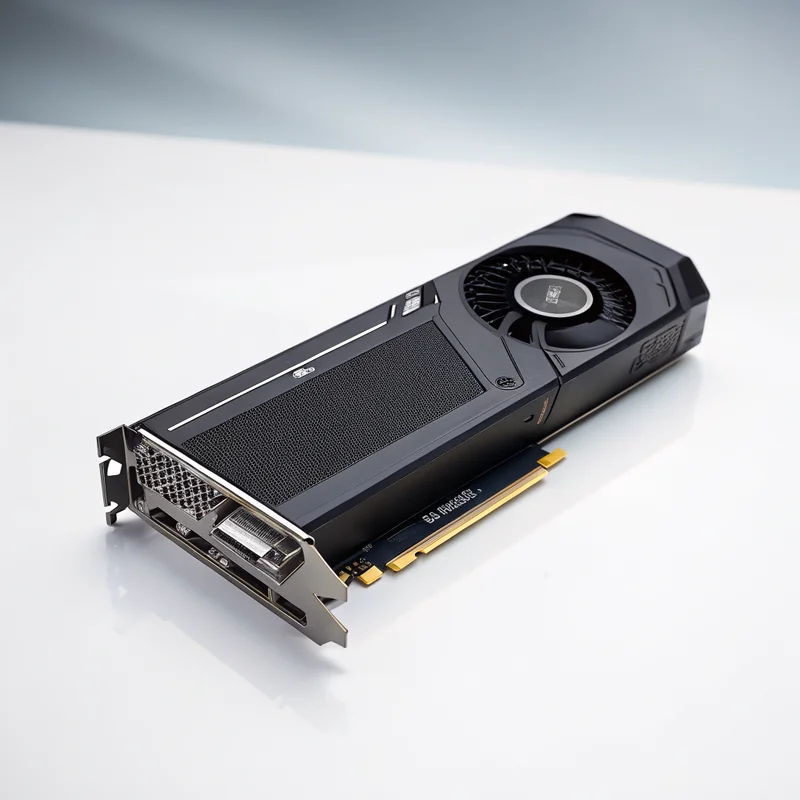
Flagship Render Studio — 96 GB
Ninety-six gigs of modern ECC VRAM — the workstation flagship for studios running multi-modal creative pipelines, AI video generation, or in-house fine-tunes.
- 96 GB GDDR7 ECC
- 1 Gbps uplink
- Workstation drivers
Studio Flagship GPU — 32 GB
Latest-gen consumer flagship in a workstation chassis. Brutal throughput for the studio running heavy image-gen pipelines or real-time video stylization for live shows.
- 32 GB GDDR7
- 1 Gbps uplink
- Liquid-cooled chassis
Enterprise GPU(12)
80GB+ VRAM, H100, multi-GPU clusters
Enterprise Render Server — 32 GB Dedicated
Bare-metal flagship GPU with 256 GB host RAM and triple-tier storage. For studios standing up an always-on generative service for their own product or paying community.
- Latest-gen flagship
- 256 GB host RAM
- Triple-tier storage
Distributed Train Cluster — 96 GB
Three datacenter cards giving the studio 96 GB combined HBM2. Built for distributed training, mid-size fine-tunes, or carving the box into multi-tenant inference slots.
- 3× datacenter V100
- HBM2 across all
- NVLink option
Enterprise Render Server — 48 GB
Datacenter-class card with ECC + RAS and MIG-partition support. For studios running an inference farm or carving one box into multiple tenant slices for creator clients.
- Datacenter card
- ECC + RAS
- Up to 7 MIG instances
Production Train Cluster — 72 GB
Three pro Ampere cards with 72 GB combined ECC VRAM. A great mid-tier training cluster for studios running production fine-tunes or multi-team inference.
- 3× pro Ampere
- 72 GB ECC total
- NVLink-ready
Enterprise Training Studio — 40 GB
Datacenter A100 — the reference card every ML team learns on. For studios running serious training, 13-30B LLM inference, or diffusion at scale on dedicated metal.
- Tensor Cores Gen3
- HBM2e memory
- 600 GB/s NVLink
Dual Render Server — 48 GB Combined
Two 24 GB cards side by side — parallel inference or model + media warm on separate cards. For studios running A/B model serving or dev + prod on one box.
- 2× consumer flagship
- Dual PCIe Gen4
- CUDA peer-to-peer
High-VRAM Render Studio — 144 GB
Three pro cards giving the studio 144 GB combined VRAM — more headroom than dual A100 80 GB at lower cost. NVLink-capable, ECC across all cards.
- 3× pro cards
- NVLink possible
- ECC across all
Dual Flagship Studio — 64 GB Combined
Two newest-gen 32 GB cards on a 44-core host, liquid-cooled. For studios running heavy training, fast 70B-class serving, or dual-tenant isolation under one roof.
- Latest-gen pair
- 44 cores host
- GPUDirect ready
Enterprise Render Cluster — 192 GB
Quad-GPU bare metal with 192 GB VRAM and 512 GB host RAM. For studios running internal foundation training or a multi-team shared generative compute pool.
- Quad-GPU
- 512 GB host RAM
- 20 TB storage
Enterprise Training Studio — 80 GB
Eighty gigs of HBM2e — fits the largest open-weights LLMs unquantized and keeps your entire generative media stack warm together. Datacenter SLA-grade.
- 80 GB HBM2e
- Full A100 architecture
- Datacenter SLA
Foundation Render Cluster — 320 GB
Training-cluster grade. Four datacenter A100 80 GB cards with 320 GB combined VRAM — enough headroom for a studio to train its own foundation model.
- 4× datacenter A100
- NVLink Bridge
- Optional InfiniBand
Flagship Render Cluster — 80 GB H-Class
The flagship. Hopper architecture, Transformer Engine, 3 TB/s HBM3 — best single-GPU performance available. For studios training their own model or running real-time 70B inference.
- Hopper architecture
- Transformer Engine
- 3 TB/s HBM3
Questions creators ask before they rent compute
- Can I run my own image-gen / ComfyUI stack on this?
- Yes — that's exactly what most of these GPU SKUs are sized for. The 24 GB and 48 GB cards comfortably hold SDXL-class models + a LoRA stack; the 80 GB tier handles top-tier image-gen plus a control net plus video diffusion without paging to disk. Install scripts for Automatic1111, ComfyUI, and Forge ship in our setup guide.
- Will I see preview latency when I'm painting live in the Design Studio?
- If your box sits in the same region as the editor, round-trip preview is typically sub-200 ms — fast enough to brush, drag, and recolor without a stutter. Pin a US-East or EU box if your store ships globally.
- I'm a music producer / video editor. Is this overkill?
- Not at all. Pick a CPU-heavy VPS for Reaper/Logic export farms, a mid-tier GPU box for DaVinci Resolve and Topaz Video AI, or scale up to a multi-card rig when you're batching a full music video reel. You only pay for the tier that fits the project.
- Do I own everything I make on the box?
- Always. Your renders, masters, weights, datasets, and source files are yours alone — nothing is mirrored into a shared training set and nothing is licensed by us downstream. Pull your work off whenever you like.
- Can I burst hard for a launch week then scale back?
- That's the monthly tier's whole point. Spin up an H100 the week of your drop, hammer it for renders + livestream encode + on-demand preview, then drop down to a CPU VPS the following Monday.
- What happens to my files between sessions?
- Local SSD persists for the life of the lease, and every box gets nightly encrypted snapshots stored in a separate region. Add the creator-tier off-site mirror for $9/mo if you want a second copy synced to your own cloud bucket.
- I want a weirder build — multi-GPU, extra NVMe, custom OS image.
- Hit [email protected] with what you're building. We've spec'd quad-GPU diffusion rigs for visual artists, RAID-heavy storage nodes for archival musicians, and bare-metal Windows boxes for Unreal-Engine indie studios. If it's buildable we'll quote it within a day.